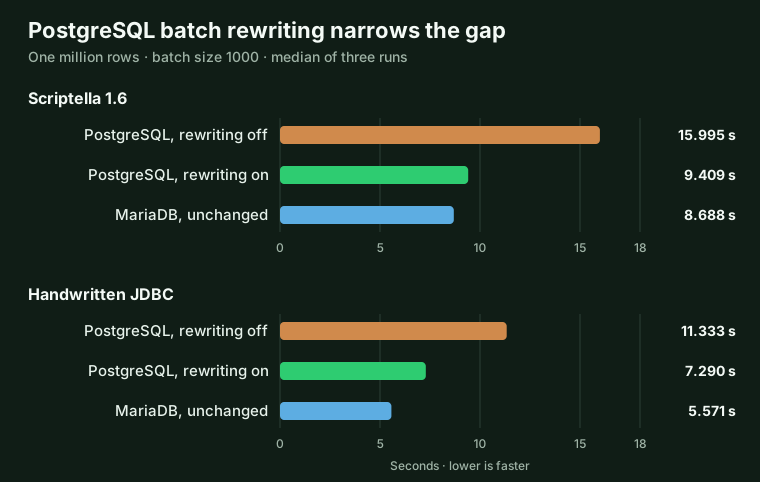
Turning on reWriteBatchedInserts=true made the Scriptella import 1.70× faster, from 15.995 seconds to 9.409. Handwritten JDBC went from 11.333 to 7.290, about 1.55×. Scriptella had been 7.307 seconds behind MariaDB. That gap is now 0.722 seconds on the unrounded medians, 9.409072 minus 8.687523. The rounded table values, 9.409 and 8.688, differ by 0.721.
Medians of three runs, batch size 1000. MariaDB stayed on its usual defaults. This follows Importing a million CSV rows. COPY remains the fastest PostgreSQL path there. This retest only asks whether the driver-default gap was real. I maintain Scriptella, and the only change here is that driver option.
A reader of the earlier comparison noticed the defaults were not doing the same job. pgJDBC leaves rewriting off. MariaDB Connector/J 3.5.7 turns useBulkStmtsForInserts on when both bulk options are left unset. Scriptella and the JDBC code had both been using those defaults.
The setting
Compatible batched inserts get rewritten into one multi-row INSERT. pgJDBC 42.7.13 leaves that off. MariaDB's bulk protocol works differently:
<connection id="db" driver="postgresql"
            url="jdbc:postgresql://postgres:5432/benchmark"
            user="benchmark" password="benchmark">
  autocommit=false
  statement.batchSize=1000
  reWriteBatchedInserts=true
</connection>
The JDBC code sets the same property. Nothing changes on the server.
Medians
All 18 imports checked out. Versions were Scriptella 1.6, pgJDBC 42.7.13, PostgreSQL 17.11, MariaDB 11.8.8, MariaDB Connector/J 3.5.7, and Java 17. The cells are medians, in seconds. The clock runs from process start through exit, so parsing and the commit count. Warmup and the checks do not.
| Import | PostgreSQL, off | PostgreSQL, on | MariaDB |
|---|---|---|---|
| Scriptella | 15.995 | 9.409 | 8.688 |
| JDBC | 11.333 | 7.290 | 5.571 |
Both got faster on every run. Scriptella's time dropped 41.2%, JDBC's 35.7%. JDBC is still 1.719 seconds behind MariaDB, down from 5.762. MariaDB is still quicker.
Scriptella is still slower than the handwritten JDBC, 1.41× with rewriting off and 1.29× with it on. Startup and a different CSV parser are inside that clock. The JDBC runs with rewriting off also drifted, from 12.845 seconds down to 10.952. Each round, the logs, and the rerun steps are in the benchmark report.
The earlier numbers stay the record of the old defaults. I reran MariaDB in this same pass, so the gap is from this retest. The table has no generated keys or triggers, and this is not a general tuning result. Adoption caveats and failure-semantics notes are in the benchmark report.
What's next
Benchmark v4 turns reWriteBatchedInserts on for both Java importers. Profiling and feedback are still pushing the import further. Reusing the parsed plan for a repeated statement, instead of parsing it on every row, is about 12.5% faster in early results.